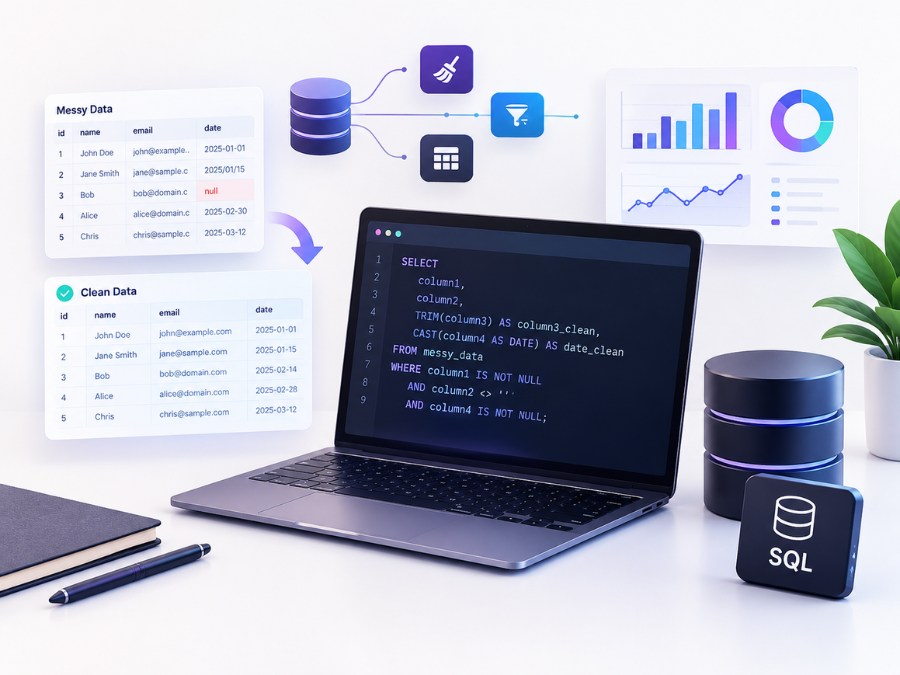
Real-world data is rarely clean. Names come in with extra spaces, dates get stored as inconsistent text, duplicate customer records pile up, and important fields end up blank. If you’ve ever opened a table and cringed at the mess staring back at you, you already understand why cleaning messy data with pure SQL is such a valuable skill for beginner data analysts and Excel users making the jump to databases.
The good news is that you don’t need Python, a separate ETL tool, or a spreadsheet full of formulas to fix most common data problems. SQL — the language every relational database understands — has everything you need built in: functions to trim whitespace, standardize casing, handle missing values, remove duplicates, and reshape messy text into something usable.
In this guide, you’ll learn practical, beginner-friendly techniques for cleaning messy data with pure SQL, using real examples you can adapt to your own tables. By the end, you’ll be comfortable tackling the most common data quality problems directly inside your database, without ever exporting a single row.
Why Clean Data Matters
Messy data isn’t just an aesthetic problem — it actively breaks reports, skews analysis, and causes bugs in downstream applications. A few examples of what messy data can cause:
- Duplicate customer records inflating your total customer count
- Inconsistent state abbreviations (
"CA"vs."California") breaking aGROUP BYreport - Extra whitespace causing
WHERE email = '[email protected]'to silently return zero rows NULLvalues crashing calculations that assume every row has a value
Cleaning your data with SQL, close to where it lives, keeps your fixes consistent and repeatable — instead of manually editing a spreadsheet every time new messy data arrives.
Common Data Problems and How to Fix Them in SQL
1. Removing Extra Whitespace
Leading and trailing spaces are one of the most common — and most invisible — data problems. Use TRIM() to remove them:
SELECT TRIM('  John Smith  ') AS CleanName;
-- Result: 'John Smith'
To clean an entire column and save the result:
UPDATE Customers
SET FullName = TRIM(FullName);
2. Standardizing Capitalization
Inconsistent capitalization ("john smith", "JOHN SMITH", "John Smith") can cause the same person to appear as multiple distinct values in a report. Use UPPER() or LOWER() to standardize:
SELECT LOWER(Email) AS StandardizedEmail
FROM Customers;
For proper-case formatting, most databases support an INITCAP() function (PostgreSQL) or require a custom expression in others, but standardizing to all lowercase is often simplest and most reliable for comparisons.
3. Handling NULL and Missing Values
Missing values can quietly break calculations and reports. COALESCE() lets you substitute a default value when a column is NULL:
SELECT
    CustomerName,
    COALESCE(PhoneNumber, 'Not Provided') AS Phone
FROM Customers;
You can also use WHERE column IS NULL to find exactly which rows are missing data, so you can decide whether to fix them or exclude them from analysis.
SELECT * FROM Customers WHERE PhoneNumber IS NULL;
4. Finding and Removing Duplicate Rows
Duplicate records are one of the most damaging messy-data problems, since they silently inflate counts and totals. A common way to find duplicates is with GROUP BY and HAVING:
SELECT Email, COUNT(*) AS Occurrences
FROM Customers
GROUP BY Email
HAVING COUNT(*) > 1;
To remove duplicates while keeping one copy of each, many databases support window functions like ROW_NUMBER():
WITH Ranked AS (
    SELECT *,
        ROW_NUMBER() OVER (PARTITION BY Email ORDER BY CustomerID) AS rn
    FROM Customers
)
DELETE FROM Ranked WHERE rn > 1;
This keeps the first row for each unique Email and removes the rest.
5. Standardizing Inconsistent Values
Free-text fields often contain inconsistent variations of the same value, like "CA", "Calif.", and "California" all meaning the same state. A CASE statement lets you map messy values to clean ones:
SELECT
    State,
    CASE
        WHEN State IN ('CA', 'Calif.', 'California') THEN 'California'
        WHEN State IN ('NY', 'N.Y.', 'New York') THEN 'New York'
        ELSE State
    END AS StandardizedState
FROM Customers;
6. Fixing Inconsistent Date Formats
Dates stored as text ("01/15/2024", "2024-01-15", "Jan 15 2024") are a frequent source of errors. Most databases provide date-parsing functions to standardize them:
SELECT CAST(OrderDateText AS DATE) AS CleanOrderDate
FROM Orders;
If CAST fails due to inconsistent formats, database-specific functions like TRY_CONVERT (SQL Server) or STR_TO_DATE (MySQL) can help handle multiple formats safely.
7. Removing Unwanted Characters
REPLACE() is useful for stripping out unwanted characters, such as currency symbols or stray punctuation, before converting text to a number:
SELECT
    CAST(REPLACE(REPLACE(PriceText, '$', ''), ',', '') AS DECIMAL(10,2)) AS CleanPrice
FROM Products;
A Simple Data-Cleaning Checklist
When you’re handed a new, messy table, work through these questions in order:
- Are there extra spaces? Use
TRIM()on text columns. - Is capitalization inconsistent? Standardize with
UPPER()orLOWER(). - Are there missing values? Decide between
COALESCE()defaults or filtering withIS NULL. - Are there duplicate rows? Find them with
GROUP BY/HAVING, remove them withROW_NUMBER(). - Are text values inconsistent? Map them to standard values with
CASE. - Are dates or numbers stored as text? Convert them with
CASTor database-specific parsing functions.
Common Mistakes to Avoid
- Running
UPDATEorDELETEwithout aWHEREclause first tested as aSELECT. Always preview which rows will be affected before modifying data. - Cleaning data without a backup. Make a copy of the table, or work in a transaction, before bulk cleaning operations.
- Assuming one cleaning pass is enough. Messy data often has multiple layered problems — whitespace and inconsistent casing and duplicates — so revisit your checklist after each fix.
Conclusion
Cleaning messy data with pure SQL is a practical, high-value skill for any beginner data analyst, Excel user, or aspiring SQL programmer. With functions like TRIM(), COALESCE(), CASE, CAST, and window functions like ROW_NUMBER(), you can fix whitespace issues, missing values, inconsistent formatting, and duplicate records directly inside your database — no external tools required.
The checklist covered in this guide — checking for whitespace, inconsistent casing, missing values, duplicates, inconsistent text, and mismatched data types — gives you a repeatable process you can apply to almost any messy table you encounter. Practice these techniques on your own datasets, and always preview changes with a SELECT before running an UPDATE or DELETE.
Once you’re comfortable cleaning messy data with pure SQL, you’ll spend far less time wrestling with broken reports and inconsistent numbers, and far more time actually analyzing the insights your data was meant to reveal.