
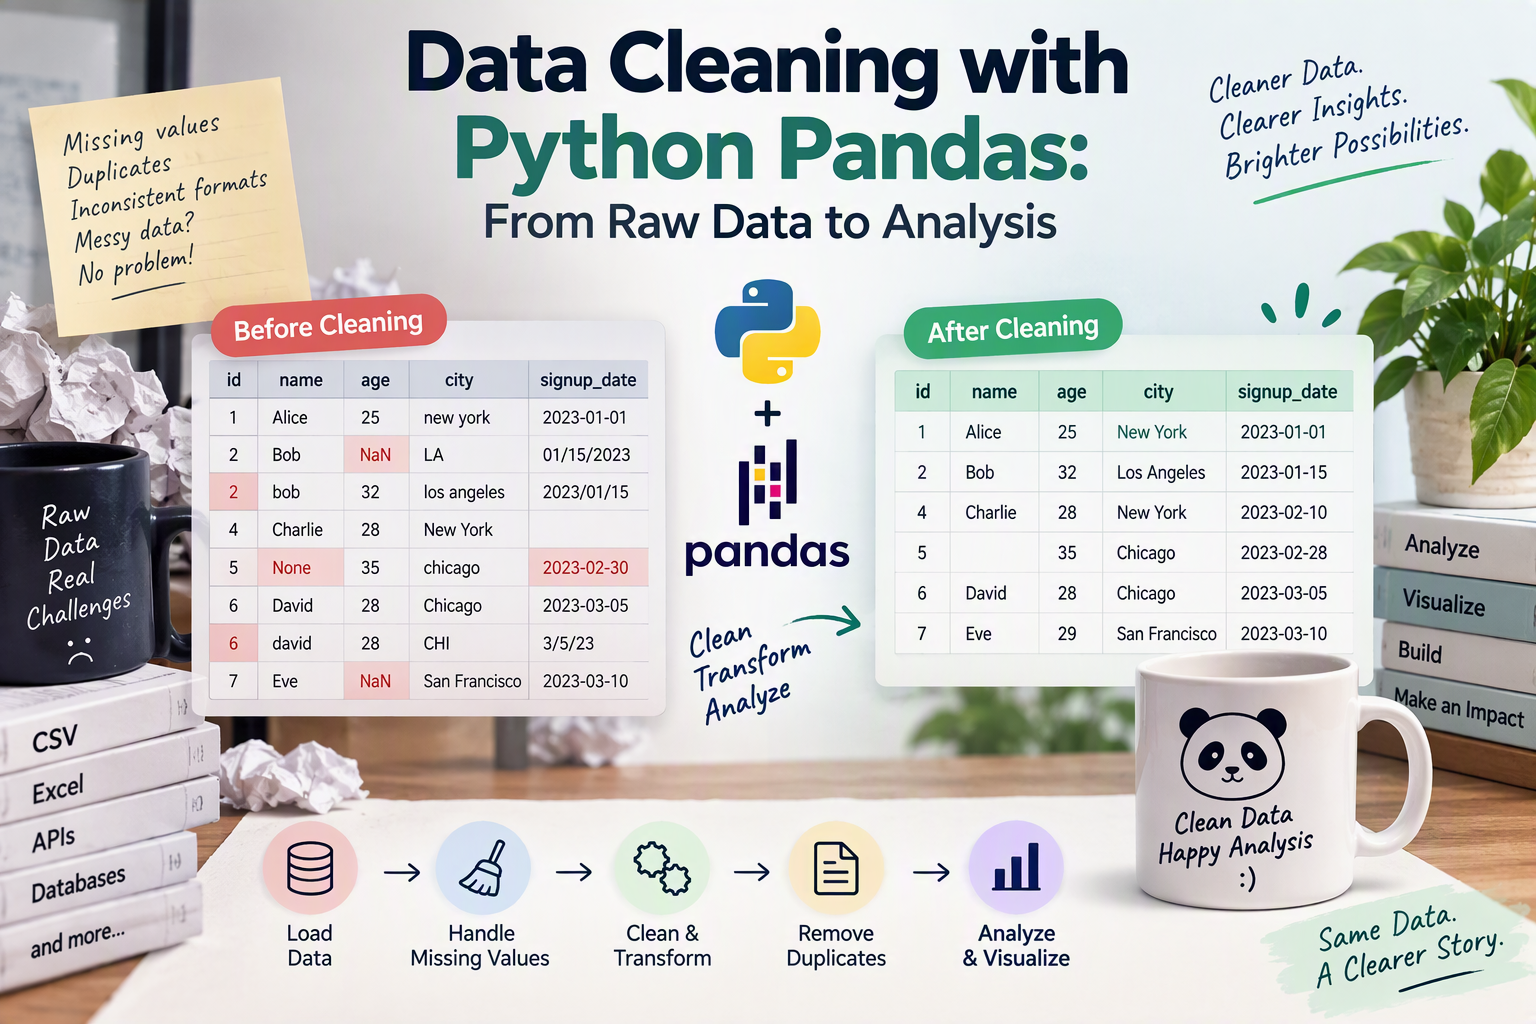
Raw data is almost never ready to analyze. Exports from online stores, contact forms, CRMs, and spreadsheets arrive with extra spaces, inconsistent capitalization, prices stored as text, duplicate rows, missing values, and the occasional test entry someone forgot to delete. Analyze that data as-is and every total, average, and chart built on top of it will be quietly wrong.
Pandas is the standard Python tool for fixing that — and for everything that comes after. In this guide, you’ll take one realistic, messy dataset through a complete workflow: load it, explore it, clean it, and analyze it. Instead of isolated snippets with placeholder names, every example runs on the same data and shows the real output, so you can see exactly what each step does.
By the end, you’ll know how to handle the tasks that make up most real-world Pandas work:
- Loading and exploring a dataset
- Selecting and filtering rows and columns
- Cleaning text, numbers stored as text, dates, duplicates, missing values, and outliers
- Adding calculated columns
- Sorting, grouping, and summarizing
- Building pivot tables and monthly trends
- Merging datasets and reshaping data
- Exporting the results
What Is Pandas?
Pandas is a free, open-source Python library for working with tabular data — data organized in rows and columns, like a spreadsheet or a database table. Its name comes from “panel data,” a term from statistics and economics.
Pandas has two main building blocks:
- A DataFrame is a whole table: rows and columns, each column with a name. Think of it as a spreadsheet in Python.
- A Series is a single column (or row) of a DataFrame: a list of values with labels.
DataFrame (the whole table)                      Series (one column: "price")

   order_id     customer      price              0       $49.00
0      1001  Maria Lopez     $49.00              1    $1,200.00
1      1002  carlos ruiz  $1,200.00              2        $9.99
2      1003   Ana Torres      $9.99
Why use Pandas instead of a spreadsheet? Because every step is code: you can rerun the whole cleanup on next month’s export in a second, see exactly what was changed, and handle files with millions of rows that would make a spreadsheet freeze.
Setting Up
Install Pandas in a virtual environment (or with uv):
pip install pandas
By convention, Pandas is always imported as pd:
import pandas as pd
Pandas versions: the output in this guide comes from Pandas 3.1. Every example also runs without warnings on Pandas 2.x. The only visible difference is in
df.info()and data types: Pandas 3 labels text columns asstr, where Pandas 2 showsobject.
The Example Dataset
Our dataset is an export of orders from a small online store that sells website templates, logo design, hosting, and SEO services. Save this as orders.csv in the same folder as your script:
order_id,order_date,customer,email,product,category,quantity,price,status
1001,2026-01-05,Maria Lopez,[email protected],Website Template,Templates,1,$49.00,Completed
1002,2026-01-07,  carlos ruiz ,[email protected],Logo Design,design,1,"$1,200.00",completed
1003,2026-01-07,Ana Torres,[email protected],Hosting Plan,Hosting,12,$9.99,Completed
1003,2026-01-07,Ana Torres,[email protected],Hosting Plan,Hosting,12,$9.99,Completed
1004,2026-01-12,Valley Dental,,SEO Audit,Marketing,1,$300.00,Pending
1005,2026-01-20,Lopez Landscaping,[email protected],Website Template,Templates,2,$49.00,Completed
1006,2026-02-02,Calexico Coffee,[email protected],Website Template,templates,2,$49.00,Completed
1007,2026-02-10,Bright Bakery,[email protected],Logo Design,Design,1,"$1,200.00",Refunded
1008,2026-02-14,Lopez Landscaping,[email protected],Hosting Plan,Hosting,,$9.99,Completed
1009,2026-02-20,Maria Lopez,[email protected],SEO Audit,Marketing,1,$300.00,Completed
1010,2026-03-03,Test User,[email protected],Website Template,Templates,1,"$49,000.00",Completed
1011,2026-03-08,Valley Dental,[email protected],Hosting Plan,HOSTING,6,$9.99,Completed
1012,2026-03-15,Calexico Coffee,[email protected],SEO Audit,Marketing,1,$300.00, completed
1013,2026-03-22,Bright Bakery,[email protected],Website Template,Templates,3,$49.00,Completed
It contains the problems you’ll see in real exports: a name with extra spaces and lowercase letters, an uppercase email, categories spelled four different ways, prices stored as text with $ and commas, a duplicated order, a missing email, a missing quantity, statuses with inconsistent capitalization, and a $49,000 “test” order.
Later, we’ll also use a second file, customers.csv:
customer,city,segment
Maria Lopez,El Centro,Freelancer
Carlos Ruiz,Calexico,Small Business
Ana Torres,Brawley,Freelancer
Valley Dental,El Centro,Small Business
Lopez Landscaping,Imperial,Small Business
Calexico Coffee,Calexico,Small Business
Bright Bakery,El Centro,Small Business
The examples build on each other, so run them in order in one script or in a Jupyter notebook.
Part 1: Load and Explore
Load the Data
import pandas as pd

pd.set_option("display.max_columns", None)  # show every column
pd.set_option("display.width", 200)

df = pd.read_csv("orders.csv")
print(df.shape)
print(df.head())
(14, 9)
   order_id  order_date        customer               email           product   category  quantity      price     status
0      1001  2026-01-05     Maria Lopez   [email protected]  Website Template  Templates       1.0     $49.00  Completed
1      1002  2026-01-07    carlos ruiz   [email protected]       Logo Design     design       1.0  $1,200.00  completed
2      1003  2026-01-07      Ana Torres     [email protected]      Hosting Plan    Hosting      12.0      $9.99  Completed
3      1003  2026-01-07      Ana Torres     [email protected]      Hosting Plan    Hosting      12.0      $9.99  Completed
4      1004  2026-01-12   Valley Dental                 NaN         SEO Audit  Marketing       1.0    $300.00    Pending
df.shape tells you the size: 14 rows and 9 columns. df.head() shows the first five rows (use df.tail() for the last five). The two set_option lines stop Pandas from hiding columns behind ... when a table is wide.
Pandas reads many formats besides CSV, including pd.read_excel() for Excel files, pd.read_json() for JSON, and pd.read_sql() for databases (see Python for Data Analysis: Accessing Your Data and SQLAlchemy).
Inspect the Structure with info()
df.info() is the single most useful first look at a new dataset:
df.info()
<class 'pandas.DataFrame'>
RangeIndex: 14 entries, 0 to 13
Data columns (total 9 columns):
 #   Column      Non-Null Count  Dtype
---  ------      --------------  -----
 0   order_id    14 non-null     int64
 1   order_date  14 non-null     str
 2   customer    14 non-null     str
 3   email       13 non-null     str
 4   product     14 non-null     str
 5   category    14 non-null     str
 6   quantity    13 non-null     float64
 7   price       14 non-null     str
 8   status      14 non-null     str
dtypes: float64(1), int64(1), str(7)
memory usage: 1.1 KB
Three problems are already visible:
priceis text (str), not a number — because of the$signs and commas. You can’t add up text.order_dateis text, so you can’t sort or group it by month yet.quantityisfloat64(a decimal number) even though quantities are whole numbers. That’s a clue: Pandas usesNaN(“not a number”) for missing values, andNaNis a float, so a numeric column with any missing value becomes a float column. The non-null counts confirm it:emailandquantityhave 13 values out of 14.
Find Missing Values, Duplicates, and Inconsistent Categories
print(df.isna().sum())
print("Duplicate rows:", df.duplicated().sum())
print(df["category"].value_counts())
order_id      0
order_date    0
customer      0
email         1
product       0
category      0
quantity      1
price         0
status        0
dtype: int64
Duplicate rows: 1
category
Templates    4
Hosting      3
Marketing    3
design       1
templates    1
Design       1
HOSTING      1
Name: count, dtype: int64
isna().sum()counts the missing values in each column.duplicated().sum()counts rows that are exact copies of an earlier row.value_counts()counts each distinct value in a column. It’s the fastest way to spot inconsistent spellings: Pandas seesDesign,design,Hosting, andHOSTINGas four different categories.
Select Columns and Rows
You’ll select data constantly, so it’s worth learning the three main ways early:
print(df[["customer", "product", "price"]].head(3))  # columns by name
print(df.loc[0, "customer"])                          # one value, by row label and column name
print(df.iloc[0:2, 0:3])                              # by position: rows 0-1, columns 0-2
         customer           product      price
0     Maria Lopez  Website Template     $49.00
1    carlos ruiz        Logo Design  $1,200.00
2      Ana Torres      Hosting Plan      $9.99
Maria Lopez
   order_id  order_date        customer
0      1001  2026-01-05     Maria Lopez
1      1002  2026-01-07    carlos ruiz
df["col"]selects one column as a Series;df[["col1", "col2"]](with double brackets) selects several columns as a DataFrame..loc[]selects by labels: row labels (the index on the left) and column names..iloc[]selects by position, like list slicing:0:2means positions 0 and 1.
Part 2: Clean the Data
Clean Text Columns
Text columns need consistent spacing and capitalization before you can group or match them. Pandas’ .str accessor applies string methods to every value in a column at once:
df["customer"] = df["customer"].str.strip().str.title()
df["email"] = df["email"].str.strip().str.lower()
df["category"] = df["category"].str.strip().str.title()
df["status"] = df["status"].str.strip().str.title()

print(df["category"].value_counts())
print(df["status"].value_counts())
category
Templates    5
Hosting      4
Marketing    3
Design       2
Name: count, dtype: int64
status
Completed    12
Pending       1
Refunded      1
Name: count, dtype: int64
.str.strip() removes extra spaces, .str.title() capitalizes each word, and .str.lower() makes emails lowercase so the same address always matches. The seven category spellings are now four clean categories, and " carlos ruiz " is now "Carlos Ruiz". (These are the same string methods from Python Basics: Variables and Data Types, applied to a whole column at once.)
Convert Prices and Dates to the Right Types
df["price"] = (
    df["price"]
    .str.replace("$", "", regex=False)
    .str.replace(",", "", regex=False)
    .astype(float)
)
df["order_date"] = pd.to_datetime(df["order_date"])

print(df[["order_date", "price"]].dtypes)
order_date    datetime64[us]
price                float64
dtype: object
Removing both the $ and the comma matters: if you only remove the $, converting "1,200.00" to a number fails with ValueError: could not convert string to float. regex=False tells Pandas to treat $ as a plain character rather than a special pattern.
pd.to_datetime() turns text into real dates, which you can sort, filter by range, and group by month. (Pandas 2 shows the type as datetime64[ns]; both work the same way.) If some dates can’t be parsed, pd.to_datetime(df["col"], errors="coerce") turns them into missing values instead of raising an error, so you can find and fix them.
Remove Duplicates
df = df.drop_duplicates()
print("Rows after removing duplicates:", len(df))
print("Duplicate order IDs left:", df["order_id"].duplicated().sum())
Rows after removing duplicates: 13
Duplicate order IDs left: 0
drop_duplicates() removes rows that are identical in every column. In real data, duplicates aren’t always exact copies — the same order might appear twice with a different timestamp — so also check the column that should be unique, like an order ID. To keep only the latest record per customer, sort first and use subset and keep:
latest = df.sort_values("order_date").drop_duplicates(subset="customer", keep="last")
Handle Missing Values
First, look at the rows with missing data before deciding what to do:
print(df[df["quantity"].isna()][["order_id", "customer", "product"]])

df["quantity"] = df["quantity"].fillna(1).astype(int)
df["email"] = df["email"].fillna("unknown")

print(df.isna().sum().sum(), "missing values left")
   order_id           customer       product
8      1008  Lopez Landscaping  Hosting Plan
0 missing values left
There’s no single right way to handle missing values; it depends on what the data means:
- Fill with a sensible default. Here, an order must have at least one item, so filling the missing quantity with
1is reasonable (in real work, confirm it with the source if you can). After filling,.astype(int)turns the column back into whole numbers. - Fill with a label like
"unknown"for text that’s useful to keep. - Fill with a statistic —
df["col"].fillna(df["col"].median())— for numeric measurements. The median is safer than the mean when there are outliers. - Drop the rows with
df.dropna(subset=["col"])when a value is essential and can’t be guessed. - Carry values forward with
df["col"].ffill()for time series where the last known value still applies.
Avoid
inplace=Trueon a column. Older tutorials writedf["col"].fillna(0, inplace=True). In Pandas 3, that does nothing todf— it changes a temporary copy, and Pandas warns that it “never works.” Always assign the result back instead:df["col"] = df["col"].fillna(0). This works the same way in every Pandas version.
Find Outliers
Outliers are values far from the rest. A common way to find them is the IQR (interquartile range) rule: anything more than 1.5 × IQR above the third quartile (or below the first) is flagged.
q1 = df["price"].quantile(0.25)
q3 = df["price"].quantile(0.75)
iqr = q3 - q1
upper = q3 + 1.5 * iqr
print(f"Upper limit: {upper:.2f}")
print(df[df["price"] > upper][["order_id", "customer", "product", "price"]])
Upper limit: 676.50
    order_id       customer           product    price
1       1002    Carlos Ruiz       Logo Design   1200.0
7       1007  Bright Bakery       Logo Design   1200.0
10      1010      Test User  Website Template  49000.0
This is an important lesson: an outlier isn’t automatically an error. The rule flagged three orders, but the two $1,200 logo design orders are real — logo design is simply the most expensive service. Only the $49,000 “Website Template” from “Test User” is clearly wrong. Statistical rules find candidates; your knowledge of the data decides what to do with them. Here, we remove only the test order:
df = df[df["customer"] != "Test User"].copy()
print("Rows:", len(df))
Rows: 12
The .copy() makes it clear that df is now its own independent table, so adding columns to it later never triggers Pandas’ “SettingWithCopyWarning” in Pandas 2.
Part 3: Analyze the Data
Filter Rows
Filtering uses boolean masks: a condition that’s True or False for each row.
completed = df[df["status"] == "Completed"]
print("Completed orders:", len(completed))

big = df[(df["status"] == "Completed") & (df["price"] >= 300)]
print(big[["order_id", "customer", "product", "price"]])

print(df[df["category"].isin(["Design", "Marketing"])][["order_id", "product"]])
print(df.query("quantity > 2 and status == 'Completed'")[["order_id", "customer", "quantity"]])
Completed orders: 10
    order_id         customer      product   price
1       1002      Carlos Ruiz  Logo Design  1200.0
9       1009      Maria Lopez    SEO Audit   300.0
12      1012  Calexico Coffee    SEO Audit   300.0
    order_id      product
1       1002  Logo Design
4       1004    SEO Audit
7       1007  Logo Design
9       1009    SEO Audit
12      1012    SEO Audit
    order_id       customer  quantity
2       1003     Ana Torres        12
11      1011  Valley Dental         6
13      1013  Bright Bakery         3
- Combine conditions with
&(and),|(or), and~(not), and wrap each condition in parentheses — Python’s operator precedence makes them necessary. .isin([...])checks whether a value is in a list..query()lets you write conditions as a readable string.- Other useful filters:
df["price"].between(10, 100), anddf["email"].str.contains("example.com").
Notice that the row numbers on the left (the index) kept their original values after filtering. That’s normal; use .reset_index(drop=True) if you want them renumbered.
Add Calculated Columns
df["revenue"] = df["quantity"] * df["price"]
df["month"] = df["order_date"].dt.to_period("M")
df["is_large_order"] = df["revenue"] >= 200

print(df[["order_id", "quantity", "price", "revenue", "month", "is_large_order"]].head())
   order_id  quantity    price  revenue    month  is_large_order
0      1001         1    49.00    49.00  2026-01           False
1      1002         1  1200.00  1200.00  2026-01            True
2      1003        12     9.99   119.88  2026-01           False
4      1004         1   300.00   300.00  2026-01            True
5      1005         2    49.00    98.00  2026-01           False
Math between columns works on every row at once — no loop required. This is called vectorization, and it’s both simpler and much faster than looping over rows. The .dt accessor works like .str, but for dates: .dt.year, .dt.month, .dt.day_name(), and .dt.to_period("M") (the month) are all available.
Sort and Rank
From here on, we’ll analyze only completed sales:
sales = df[df["status"] == "Completed"].copy()
print(sales.sort_values(["revenue", "customer"], ascending=[False, True])[["order_id", "customer", "revenue"]].head(4))
print(sales.nlargest(3, "revenue")[["customer", "revenue"]])
    order_id         customer  revenue
1       1002      Carlos Ruiz   1200.0
12      1012  Calexico Coffee    300.0
9       1009      Maria Lopez    300.0
13      1013    Bright Bakery    147.0
           customer  revenue
1       Carlos Ruiz   1200.0
9       Maria Lopez    300.0
12  Calexico Coffee    300.0
Sorting by more than one column breaks ties: two orders have $300 of revenue, so the second column (customer, A to Z) decides their order. nlargest() and nsmallest() are shortcuts for “top N” lists.
Group and Summarize
groupby() is one of the most powerful tools in Pandas. It works in three steps — split the data into groups, apply a calculation to each group, and combine the results:
print(sales.groupby("category")["revenue"].sum().sort_values(ascending=False))
category
Design       1200.00
Marketing     600.00
Templates     392.00
Hosting       189.81
Name: revenue, dtype: float64
To calculate several statistics at once, use .agg() with named aggregations — each new column gets a name, a source column, and a function:
summary = sales.groupby("customer").agg(
    orders=("order_id", "count"),
    total_revenue=("revenue", "sum"),
    avg_order=("revenue", "mean"),
).sort_values("total_revenue", ascending=False)
print(summary.round(2))
                   orders  total_revenue  avg_order
customer
Carlos Ruiz             1        1200.00    1200.00
Calexico Coffee         2         398.00     199.00
Maria Lopez             2         349.00     174.50
Bright Bakery           1         147.00     147.00
Ana Torres              1         119.88     119.88
Lopez Landscaping       2         107.99      54.00
Valley Dental           1          59.94      59.94
That’s a complete customer report in five lines. Common aggregation functions include "sum", "mean", "median", "count", "nunique" (number of distinct values), "min", and "max".
Build a Pivot Table
A pivot table summarizes data across two dimensions, just like in Excel:
pivot = sales.pivot_table(
    index="month",
    columns="category",
    values="revenue",
    aggfunc="sum",
    fill_value=0,
)
print(pivot)
category  Design  Hosting  Marketing  Templates
month
2026-01   1200.0   119.88        0.0      147.0
2026-02      0.0     9.99      300.0       98.0
2026-03      0.0    59.94      300.0      147.0
index sets the rows, columns sets the columns, values is what to summarize, and fill_value=0 replaces empty combinations (no Design sales in February) with zero.
To simply count combinations, pd.crosstab() is a shortcut. Here it shows order statuses by category, using all orders:
print(pd.crosstab(df["category"], df["status"]))
status     Completed  Pending  Refunded
category
Design             1        0         1
Hosting            3        0         0
Marketing          2        1         0
Templates          4        0         0
Analyze Trends Over Time
With a real date column, Pandas can summarize data by any time period. resample() groups by time — here, monthly totals:
monthly = sales.set_index("order_date")["revenue"].resample("MS").sum()
print(monthly)
print(monthly.pct_change().round(3))
order_date
2026-01-01    1466.88
2026-02-01     407.99
2026-03-01     506.94
Freq: MS, Name: revenue, dtype: float64
order_date
2026-01-01      NaN
2026-02-01   -0.722
2026-03-01    0.243
Freq: MS, Name: revenue, dtype: float64
"MS" means “month start” (use "W" for weeks or "QS" for quarters). pct_change() calculates the change from one period to the next: revenue fell 72.2% in February and grew 24.3% in March. January is NaN because there’s no earlier month to compare it with. Use .rolling(3).mean() for moving averages.
Combine Datasets with merge()
To add each customer’s city and segment, merge the sales with customers.csv. It works just like a SQL join (see SQL JOINs Explained):
customers = pd.read_csv("customers.csv")
merged = sales.merge(customers, on="customer", how="left", validate="many_to_one")
print(merged[["customer", "city", "segment", "revenue"]].head())
print(merged.groupby("city")["revenue"].sum().sort_values(ascending=False))
            customer       city         segment  revenue
0        Maria Lopez  El Centro      Freelancer    49.00
1        Carlos Ruiz   Calexico  Small Business  1200.00
2         Ana Torres    Brawley      Freelancer   119.88
3  Lopez Landscaping   Imperial  Small Business    98.00
4    Calexico Coffee   Calexico  Small Business    98.00
city
Calexico     1598.00
El Centro     555.94
Brawley       119.88
Imperial      107.99
Name: revenue, dtype: float64
how="left"keeps every sale, even if a customer isn’t in the second file. ("inner"keeps only matches,"outer"keeps everything, and"right"keeps every row of the second table.)validate="many_to_one"makes Pandas raise an error if a customer appears more than once incustomers.csv, which would silently duplicate rows in the result.
Notice that Carlos Ruiz matched his city. That only worked because we cleaned " carlos ruiz " earlier — merges match text exactly, so cleaning always comes first. To check how many rows matched, add indicator=True:
check = df.merge(customers, on="customer", how="left", indicator=True)
print(check["_merge"].value_counts())
_merge
both          12
left_only      0
right_only     0
Name: count, dtype: int64
All 12 orders found their customer. Any left_only rows would be orders with no matching customer — usually a sign of a spelling difference to fix.
To stack tables with the same columns — like adding next month’s orders — use pd.concat():
april = pd.DataFrame({
    "order_id": [1014, 1015],
    "customer": ["Maria Lopez", "Ana Torres"],
    "revenue": [49.0, 300.0],
})
all_orders = pd.concat([sales[["order_id", "customer", "revenue"]], april], ignore_index=True)
print(len(sales), "+", len(april), "=", len(all_orders))
10 + 2 = 12
Reshape Wide and Long Data
Data comes in two shapes. Wide data has one column per category, like the pivot table above. Long (or “tidy”) data has one row per measurement, which is what most charting libraries and many analyses expect. melt() converts wide to long (and pivot_table() goes the other way):
wide = pivot.reset_index()
long = wide.melt(id_vars="month", var_name="category", value_name="revenue")
print(long.head(6))
     month category  revenue
0  2026-01   Design  1200.00
1  2026-02   Design     0.00
2  2026-03   Design     0.00
3  2026-01  Hosting   119.88
4  2026-02  Hosting     9.99
5  2026-03  Hosting    59.94
Map Values and Create Categories
Two more transformations come up constantly. .map() translates values using a dictionary (see Python Basics: Lists and Dictionaries), and pd.cut() groups numbers into labeled ranges:
tier = {"Templates": "Product", "Hosting": "Recurring", "Design": "Service", "Marketing": "Service"}
df["revenue_type"] = df["category"].map(tier)
df["size"] = pd.cut(df["revenue"], bins=[0, 100, 500, float("inf")], labels=["Small", "Medium", "Large"])
print(df[["product", "category", "revenue_type", "revenue", "size"]].head())
            product   category revenue_type  revenue    size
0  Website Template  Templates      Product    49.00   Small
1       Logo Design     Design      Service  1200.00   Large
2      Hosting Plan    Hosting    Recurring   119.88  Medium
4         SEO Audit  Marketing      Service   300.00  Medium
5  Website Template  Templates      Product    98.00   Small
Values that aren’t in the dictionary become NaN, which makes .map() a quick way to spot unexpected categories. For logic that’s too complex for a dictionary, .apply() runs your own function on each value — but try a vectorized approach first, because .apply() is much slower on large data.
Part 4: Export the Results
summary.round(2).to_csv("customer_summary.csv")
sales.drop(columns="month").to_json("sales.json", orient="records", date_format="iso", indent=2)
customer_summary.csv now contains:
customer,orders,total_revenue,avg_order
Carlos Ruiz,1,1200.0,1200.0
Calexico Coffee,2,398.0,199.0
Maria Lopez,2,349.0,174.5
Bright Bakery,1,147.0,147.0
Ana Torres,1,119.88,119.88
Lopez Landscaping,2,107.99,54.0
Valley Dental,1,59.94,59.94
Use index=False with to_csv() when the index is just row numbers you don’t need. For JSON, we dropped the helper month column because JSON can’t store Pandas’ “Period” type — a good reminder to export plain columns. Other formats include to_excel() (which needs the openpyxl package) and to_sql() for databases.
To turn these results into charts, see Python Data Visualization: A Practical Guide to Charts & Graphs.
Common Pandas Mistakes
- Using
inplace=Trueon a column.df["col"].fillna(0, inplace=True)does nothing in Pandas 3. Assign the result back:df["col"] = df["col"].fillna(0). - Forgetting parentheses when combining conditions.
df[df["a"] > 1 & df["b"] < 5]raises an error or gives wrong results. Writedf[(df["a"] > 1) & (df["b"] < 5)]. - Using
and/orinstead of&/|. Python’sanddoesn’t work on whole columns; Pandas needs&and|. - Doing math on numbers stored as text. Check
df.info()first, and convert with.astype()orpd.to_numeric(). - Comparing to
NaNwith==.NaN == NaNisFalse. Use.isna()and.notna()instead. - Looping over rows.
for index, row in df.iterrows()is slow and rarely needed. Use column operations instead. - Merging before cleaning.
"Carlos Ruiz"and" carlos ruiz "don’t match. Clean the key columns first, and useindicator=Trueto check the result. - Deleting every outlier automatically. Review flagged values before removing them; some are your most important data.
- Modifying a filtered table without
.copy(). It can triggerSettingWithCopyWarningin Pandas 2. Add.copy()when you filter a DataFrame you plan to change.
Pandas Cheat Sheet
| Task | Code |
|---|---|
| Load a CSV | df = pd.read_csv("file.csv") |
| First look | df.head(), df.info(), df.describe(), df.shape |
| Missing values | df.isna().sum() |
| Count values | df["col"].value_counts() |
| Select columns | df[["a", "b"]] |
| Select by label / position | df.loc[row, "col"], df.iloc[0:5, 0:3] |
| Filter rows | df[(df["a"] > 1) & (df["b"] == "x")] |
| Clean text | df["col"].str.strip().str.title() |
| Convert types | .astype(float), pd.to_datetime(), pd.to_numeric() |
| Fill missing values | df["col"] = df["col"].fillna(value) |
| Drop rows with missing values | df.dropna(subset=["col"]) |
| Remove duplicates | df.drop_duplicates() |
| New column | df["c"] = df["a"] * df["b"] |
| Sort | df.sort_values("col", ascending=False) |
| Group and summarize | df.groupby("col")["val"].sum() or .agg(...) |
| Pivot table | df.pivot_table(index=..., columns=..., values=..., aggfunc="sum") |
| Time periods | df.set_index("date")["val"].resample("MS").sum() |
| Merge | df.merge(other, on="key", how="left") |
| Stack tables | pd.concat([df1, df2], ignore_index=True) |
| Wide to long | df.melt(id_vars=..., var_name=..., value_name=...) |
| Export | df.to_csv("out.csv", index=False) |
Conclusion
Most real-world Pandas work follows the same pattern you just used: load the data, explore it with info(), isna(), and value_counts(), clean the text, types, duplicates, missing values, and outliers, and then analyze it with filters, calculated columns, groupby(), pivot tables, time-based summaries, and merges — before exporting the results.
The cleaning steps aren’t just preparation; they decide whether your answers are right. Without them, this dataset would have reported seven product categories instead of four, counted one order twice, missed Carlos Ruiz’s city in the merge, and added a fake $49,000 sale to March’s revenue. Save your cleaning steps in a script, and next month’s export takes seconds instead of an afternoon.
For a deeper look at the cleaning techniques themselves using plain SQL, see Cleaning Messy Data with Pure SQL.