
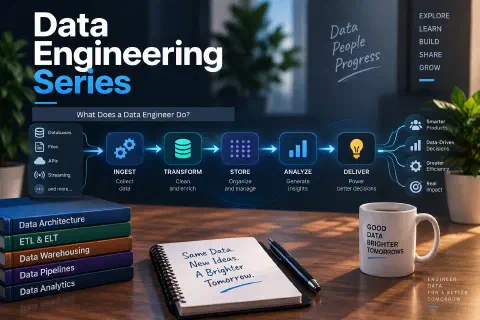
Data Engineering series, Part 2 of 5. Previous: What Is a Data Engineer?
- What Is a Data Engineer?
- What Does a Data Engineer Do? (you are here)
- Data Engineering Tools: SQL, Python, and Essential Technologies
- What Is a Data Pipeline?
- How to Become a Data Engineer
A data engineer builds and maintains data pipelines, designs the databases and warehouses where data is stored, keeps the data accurate, and automates the jobs that deliver it to the people who need it. In other words, they make sure the right data arrives in the right place, in the right shape, on time, every day.
In Part 1 you learned what data engineering is. This article shows what the job looks like in practice: the responsibilities, a typical day, the work behind the scenes, and the skills you need.
The Core Responsibilities
Titles and teams differ, but most data engineers are responsible for the following.
1. Building and maintaining data pipelines
A data pipeline is an automated process that moves data from a source to a destination and prepares it along the way. Data engineers design these pipelines, write the code, test them, and fix them when they break. Part 4 covers pipelines in depth.
2. Designing databases and data models
They decide how data is organized: which tables exist, how they relate, what each column holds, and how to make queries fast. Good design prevents duplicates, inconsistencies, and slow reports. See database design for the fundamentals.
3. Extracting, transforming, and loading data (ETL and ELT)
Data engineers pull data from sources (extract), clean and reshape it (transform), and store it in a destination (load), in either the ETL or ELT order. The details are in ETL vs ELT.
4. Ensuring data quality
Bad data leads to bad decisions, so engineers add checks that catch problems early: missing values, duplicates, wrong formats, and impossible numbers. You will see an example below.
5. Automating and scheduling
Nobody should run data jobs by hand every morning. Engineers schedule pipelines to run on time, retry when something fails, and alert the team when a problem needs attention.
6. Optimizing performance and cost
Queries that were fast on a small table can crawl on a large one, and cloud storage and compute cost money. Engineers tune queries, choose efficient storage, and avoid waste. See why your SQL query is slow.
7. Protecting and governing data
Data often includes personal or sensitive information. Engineers control who can access it, encrypt it, and follow privacy rules. See database security and privacy and data privacy for business.
8. Collaborating and documenting
Data engineers work with analysts, data scientists, software developers, and business teams to understand what data they need. They also document how pipelines work, so others can understand and maintain them.
A Day in the Life
Every team is different, but a typical day might look like this:
| Time | Activity |
|---|---|
| Morning | Check that the overnight pipelines finished, and review any alerts or failures |
| Mid-morning | Investigate a failed job: a source file changed format and broke the transformation, so fix it and re-run |
| Late morning | Meet with analysts who need a new dataset for a sales report |
| Afternoon | Build the new pipeline, writing SQL and Python, with tests |
| Late afternoon | Review a teammate’s code, and tune a slow query that is delaying a dashboard |
| End of day | Update the documentation and plan tomorrow’s work |
Notice how much of the work is maintenance and problem-solving, not only building new things.
Working With Databases
Databases are at the center of the job. Data engineers write SQL every day to create tables, load and transform data, and check results. They work with relational databases such as PostgreSQL and MySQL, and with cloud data warehouses built for analysis. If you are new to this, start with PostgreSQL for beginners and learn SQL joins and window functions.
Automation and Scheduling
A pipeline that only runs when someone remembers to start it isn’t a pipeline. Engineers use schedulers and orchestration tools to run jobs on a timetable, in the right order, and with retries.
The simplest scheduler is cron on Linux. This line runs a script every night at 2:00 AM:
0 2 * * * /usr/bin/python3 /opt/pipelines/orders.py
More advanced orchestration tools handle dependencies (“run job B only after job A succeeds”), retries, logs, and alerts. Part 3 lists the common ones. For simpler business automation without code, tools like Power Automate cover a similar need on a smaller scale.
Data Quality in Practice
Here is a small example of the kind of check a data engineer writes. It looks at a table of orders and reports which rules fail:
import pandas as pd

orders = pd.DataFrame({
    "order_id": [1, 2, 2, 4],
    "customer": ["Ana", "Luis", "Luis", None],
    "amount": [35.5, 120.0, 120.0, -5.0],
})

checks = {
    "table has rows": len(orders) > 0,
    "no missing customers": orders["customer"].notna().all(),
    "order_id is unique": orders["order_id"].is_unique,
    "amount is not negative": (orders["amount"] >= 0).all(),
}

for name, passed in checks.items():
    print("PASS" if passed else "FAIL", "-", name)

failed = [name for name, passed in checks.items() if not passed]
if failed:
    print(f"{len(failed)} check(s) failed")
Output:
PASS - table has rows
FAIL - no missing customers
FAIL - order_id is unique
FAIL - amount is not negative
3 check(s) failed
In a real pipeline, a failed check would stop the job or send an alert, so bad data never reaches a dashboard. You can run the same kind of check directly in SQL. For example, this finds duplicate order IDs:
SELECT order_id, COUNT(*) AS copies
FROM orders
GROUP BY order_id
HAVING COUNT(*) > 1;
To learn more about cleaning, see cleaning messy data with SQL and data cleaning with Pandas.
Monitoring and Reliability
Pipelines fail for ordinary reasons: a server goes down, a file arrives late, an API changes, or the data volume suddenly doubles. Engineers add:
- Logging, so you can see what happened and when.
- Alerts, so the team knows quickly when something breaks.
- Retries, so temporary problems fix themselves.
- Backups and recovery plans, so data can be restored. See disaster recovery.
The idea is similar to monitoring a website, as in the Uptime Kuma guide, but applied to data jobs.
Skills a Data Engineer Needs
| Technical skills | Soft skills |
|---|---|
| SQL for querying and transforming data | Problem-solving to find why something broke |
| Python for automation and data processing | Communication with technical and non-technical people |
| Databases and data modeling | Attention to detail, because small errors spread |
| Cloud platforms and basic networking | Curiosity to learn new tools |
| Git for version control | Collaboration and willingness to document |
| Linux command line and Docker basics | Patience with messy, unpredictable data |
If you want to start building these, try Python basics, Git, and Docker.
How the Role Changes by Company
- Small companies and startups: you are often a generalist. One person might build pipelines, design the database, and make dashboards.
- Large companies: roles are specialized. One team might handle ingestion, another the data warehouse, and another the platform and tooling.
- Industry matters too: healthcare and finance have strict rules for security and privacy, while e-commerce may focus on speed and large volumes.
Common Challenges
- Messy sources. Data arrives with missing values, inconsistent formats, and surprises.
- Changing schemas. A source system adds or renames a column, and your pipeline breaks.
- Silent failures. A job “succeeds” but loads incomplete data, which is worse than failing loudly.
- Scale. Something that worked with thousands of rows gets slow with millions.
- Cost. Cloud resources add up if they aren’t managed.
Good engineering habits (tests, monitoring, documentation) are how experienced engineers handle all of these.
Frequently Asked Questions
What does a data engineer do every day?
They monitor and fix pipelines, write SQL and Python to move and transform data, design or improve databases, review code, and work with analysts and developers to deliver the data people need.
Do data engineers build dashboards?
Usually not. They prepare the data and make it available, and analysts or BI developers build the dashboards. In small teams, one person may do both.
What is the difference between ETL and data engineering?
ETL (extract, transform, load) is one process that data engineers build. Data engineering is the broader field that also covers databases, automation, quality, performance, and security.
Do data engineers need to know machine learning?
Not necessarily. Some understanding helps, since they often prepare data for models, but building models is mainly a data scientist’s job. See What Is Data Science?.
How much SQL does a data engineer need?
A lot. SQL is the core skill, from basic queries and joins to window functions, performance tuning, and data modeling.
Is data engineering stressful?
It can be when a pipeline breaks and people are waiting for data. Good monitoring, testing, and clear documentation reduce that stress.
Conclusion
A data engineer’s job is to make data trustworthy and available: building pipelines, designing databases, checking quality, automating jobs, and keeping everything running smoothly. The work blends programming, databases, and problem-solving, and it supports almost everything an analyst or data scientist does.
In Part 3, you will learn the tools behind the work: Data Engineering Tools: SQL, Python, and Essential Technologies.
Next in the Data Engineering series: Data Engineering Tools: SQL, Python, and Essential Technologies